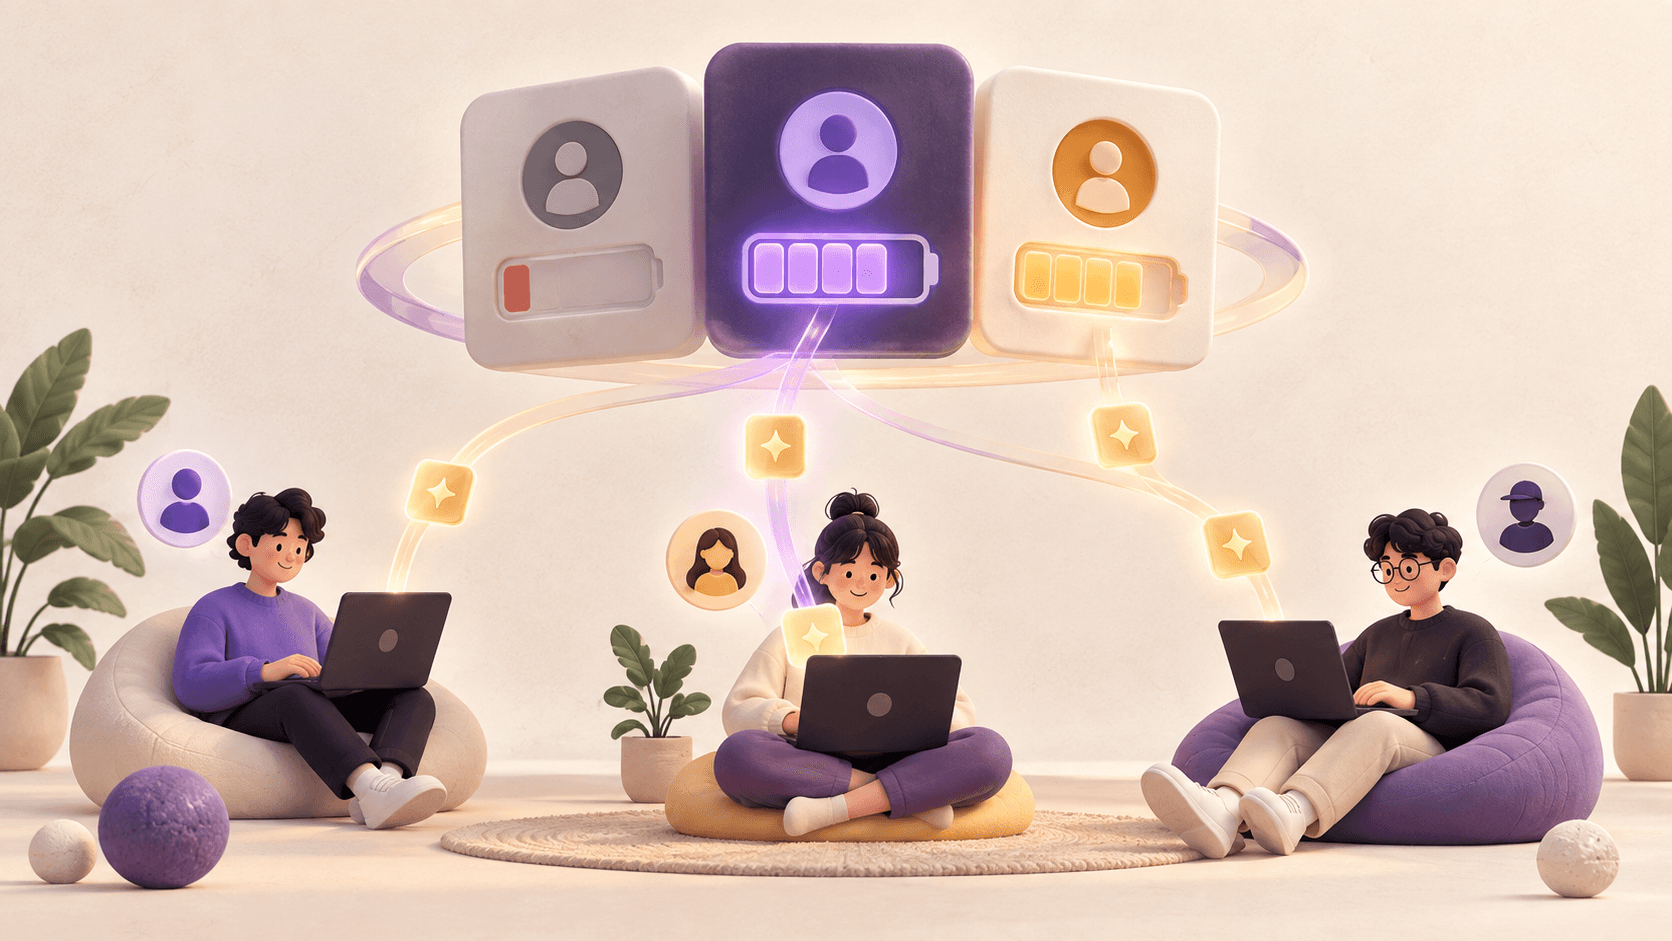
This post assumes several accounts are already available for Claude Code or Codex, and multiple people want to share those accounts' unused capacity. One person might manage several accounts, or several people might contribute accounts to a shared pool. Each user does not need to own multiple accounts. The pool they can use needs to contain more than one.
For example, suppose three people share Claude Code accounts A, B, and C. One person has nearly exhausted A's allowance during a long task, while B and C still have capacity. Instead of checking each account and manually changing logins every time, a server selects an account with room left and assigns it to the person who needs it.
Claude Code needs a pool of Claude Code accounts, and Codex needs a pool of Codex accounts. If you use only one tool, you only need accounts for that tool. A Claude Code account and a Codex account cannot exchange their unused allowances.
Each account's usage limits still apply. People assigned the same account share that account's allowance. Connecting one account to several computers does not increase its limit, and once every account in the pool has reached its limit, there is no spare capacity left to assign. The purpose of this setup is to make use of unused capacity across accounts that are already available.
A server that registers the accounts, checks their status, and assigns credentials must also be in place. I call this the credential server throughout this post. Users receive credentials for the account it selects and run the tool on their own computers. As usage accumulates, the server prepares credentials for another account with capacity available.
The rest of this post assumes that credential server already exists and explains how to connect shared accounts on a personal computer. I normally work with my own subscription account and switch to a shared account when needed. The setup keeps the two accounts' logins and histories separate, passes credentials only to the process that needs them, and prepares credentials for the next launch. I also cover how to apply a different account to a session that is already running.
Where the two tools read credentials
At startup, Claude Code checks several credential sources in a defined order. For the sources relevant to this setup, shell variables such as ANTHROPIC_AUTH_TOKEN or ANTHROPIC_API_KEY take precedence. Next comes CLAUDE_CODE_OAUTH_TOKEN, which holds a subscription token, followed by the login saved through /login. I pass the shared account's token through CLAUDE_CODE_OAUTH_TOKEN. If the first two variables remain in the shell, they take precedence over it, so I clear them. Claude Code authentication documentation
Logins are stored separately for each configuration directory. The default is ~/.claude, and CLAUDE_CONFIG_DIR changes it. On macOS, login credentials are stored in Keychain. A different configuration directory also gets its own associated Keychain entry.
For Codex, codex login creates the auth.json file used for authentication. The file lives under CODEX_HOME, which defaults to ~/.codex. The CLI, IDE extension, and desktop app share this login. Depending on the configuration, credentials can also be stored in the operating system's credential store; this post uses file storage. Codex authentication documentation
| Item | Claude Code | Codex |
|---|---|---|
| Where shared credentials go | The CLAUDE_CODE_OAUTH_TOKEN environment variable |
The auth.json file |
| How accounts are separated | CLAUDE_CONFIG_DIR |
CODEX_HOME |
| When new credentials take effect | When a new session starts | When a new session starts |
| What to watch for with shared accounts | A leftover ANTHROPIC_API_KEY takes precedence |
Logging out or logging in again can disconnect other clients using those credentials |
Both tools select their credentials when a session starts and continue using that account for the session. A configuration directory can hold only one account at a time; using two accounts in the same directory can overwrite login state and history. The rest of the setup follows from these two constraints.
Connecting shared accounts on each computer
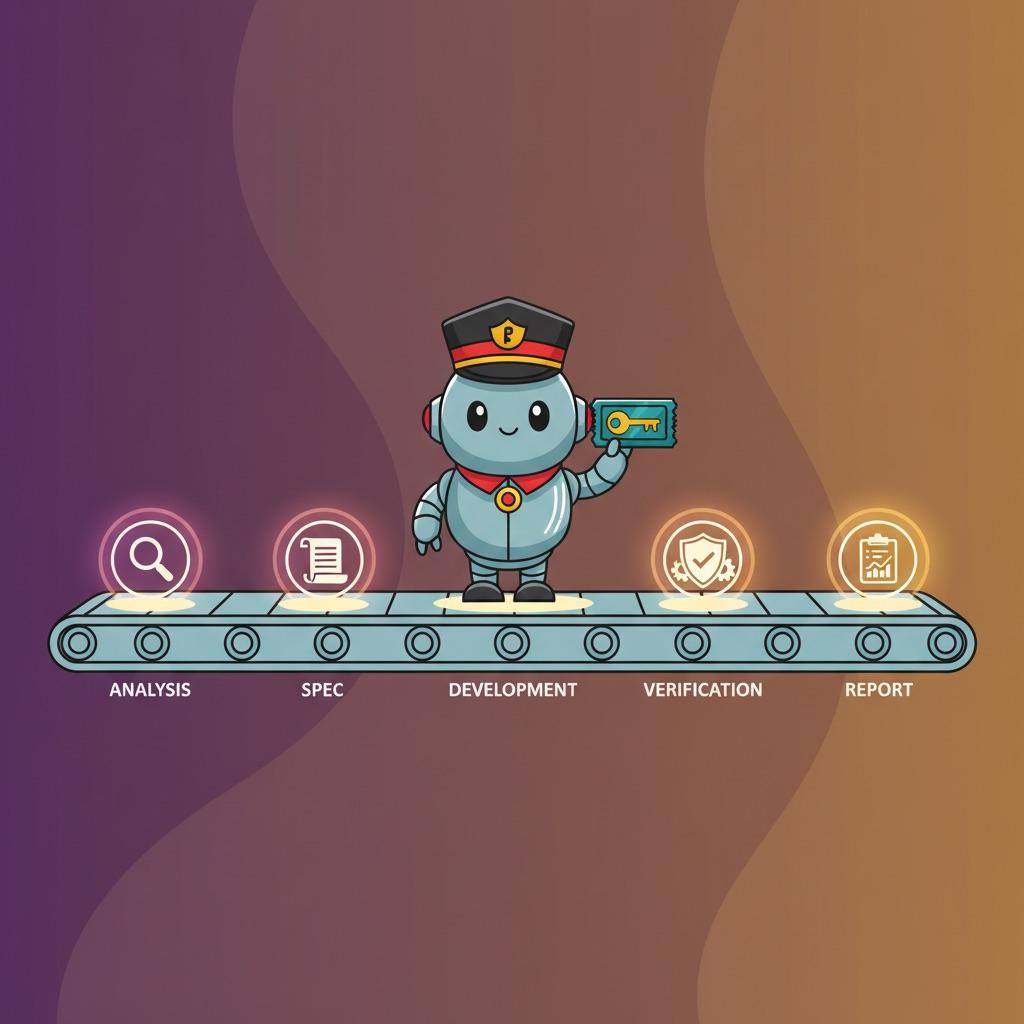
The setup has four parts. The diagram shows Claude Code; I explain the differences for Codex below.


- Two configuration directories. My own account uses the default directory, while the shared account uses a dedicated one. Only settings that define how I work are shared through symbolic links.
- A shared-account launcher. This is a shell function. At launch, it fetches the latest token from the credential server, selects the dedicated directory, and passes the token only to that invocation. Running plain
claudestill uses my own account. - Keychain. It stores the key used to access the credential server and a copy of the most recently received token. There are no plaintext files for those values.
- A rotation worker. This is a shell script kept running by launchd. Every 10 minutes, it checks the current token's status. When the account is approaching its limit, it fetches a new token and replaces the cached copy.
Codex follows the same pattern. Its rotation worker updates auth.json in the dedicated directory instead of Keychain, and its launcher simply points CODEX_HOME at that directory.
Separate accounts by directory and share settings through links
Pointing CLAUDE_CONFIG_DIR at a new directory immediately separates the account. However, Claude Code uses that directory for both authentication and configuration. Starting with an empty directory means no plugins, skills, commands, or hooks: it looks like a fresh installation. I therefore separate account-specific data from working preferences, then link only the latter back to the default directory. Changing the directory also moves ~/.claude.json to .claude.json inside the new directory. Claude Code directory documentation
| Category | Examples | Treatment |
|---|---|---|
| Account | .claude.json (login session, onboarding state, project trust, personal MCP servers), Keychain login |
Separate for each directory |
| Work history | projects/ (session history, automatic memory), history.jsonl |
Separate for each directory |
| Working preferences | settings.json, CLAUDE.md, skills/, commands/, plugins/ |
Symbolic links to the default directory |
The two accounts keep separate conversation histories. A conversation started with the shared account cannot be resumed from my personal account with --resume. Personal MCP servers must also be registered separately in the dedicated directory. Linked settings, however, stay shared: a change made from either side applies to both.
One detail can break those links. When an application writes settings to a temporary file and renames it into place, it may replace the symbolic link itself with a regular file instead of updating the link's target. After that, the two directories' settings drift apart. I encountered this with settings.json. If a change on one side does not appear on the other, first check whether the entry in the dedicated directory is still a symbolic link.
The first-run screens in a new directory
Handling the first-run screens took the most time in this setup. A new directory has no onboarding state, so the first interactive launch shows theme and login-method selection screens. These are separate from token authentication, which makes the situation confusing: claude -p can work perfectly. If I casually log in at that point, my personal login gets saved in the dedicated directory. From then on, even the shared-account launcher connects to my own account.
To avoid that, I copy only the markers indicating completed onboarding from the default directory's .claude.json into the dedicated one. Copying hasCompletedOnboarding alone did not suppress the theme screen. Several onboarding-related keys were needed. I identified them by capturing and comparing the first-run screens in a pseudo-terminal. I do not copy oauthAccount, because it carries account identity with it.
The lesson was to test interactive mode separately even when -p works. After changing the setup, I open an interactive session and run /status to see which authentication is in use. A shared token appears as CLAUDE_CODE_OAUTH_TOKEN; my own account shows the login method and email address. If the login selection screen still appears, I exit without choosing anything.
Three directories for Codex
Codex uses CODEX_HOME for the same purpose. I split it into three directories.
| Directory | Account | What writes auth.json |
|---|---|---|
~/.codex |
My ChatGPT login | codex login |
| Dedicated shared-account directory | Shared account | The rotation worker, every 10 minutes |
| Dedicated API-key directory | OpenAI API key with usage-based billing | The launcher, using the Keychain key at launch |
I link config.toml, AGENTS.md, skills, and hooks to the default directory. Each directory keeps its own auth.json, sessions, history, and state database. Multiple processes writing to the same state database can corrupt it.
The main reason I separated Codex directories was the trouble caused by logging out. In this shared-account setup, running codex logout or codex login while connected to the shared account removes the local file and invalidates credentials on the provider side. Other people and devices using the same credentials can be disconnected too. Keeping the shared account in the default directory makes it easy to log out by habit and disrupt everyone else. A dedicated directory means plain codex acts on my own account instead. To remove only the local shared credentials, I delete that directory's auth.json rather than logging out. The rotation worker restores it within 10 minutes.
Pass credentials only to the process being launched
The simplest way to use a shared token is to set CLAUDE_CODE_OAUTH_TOKEN and CLAUDE_CONFIG_DIR globally in a shell startup file. That convenience creates two problems. Because the environment variable takes precedence over the saved login, plain claude connects to the shared account instead of my own. Other processes launched from that shell, including editors, also inherit the token. I avoid passing tokens as command-line arguments as well, because they become visible in the process list.
The launcher therefore sets these variables only inside a subshell and starts the tool there. The token exists in that process and its children, but not in the shell from which I invoked it. This is not complete isolation, since child processes still inherit environment variables. It does, however, greatly narrow the scope compared with setting them for the entire shell.
At launch, I fetch the token directly from the credential server. The Keychain copy is refreshed every 10 minutes, so it can lag behind if the server rotates a token between updates. I have seen the server hold newer credentials than the local copy. It normally responds within 0.1 seconds, so the request adds little delay. I fall back to the cached copy only if there is no response within 5 seconds.
For Codex, the rotation worker keeps auth.json in the dedicated directory current, so the launcher only needs to set CODEX_HOME. The worker downloads credentials to a temporary file, checks that they are valid JSON, and replaces the existing file only if the contents differ. That avoids unnecessarily rewriting a file the running tool may be reading every 10 minutes. But it does not mean keeping an old copy indefinitely: the credential server handles token renewal, and even the same account can receive newly issued credentials. I have seen an old copy become invalid on the server.
Store keys and token copies in Keychain
I keep the credential server's access key and cached token only in macOS Keychain. Granting the security command access when storing them lets the launchd worker read them without a password prompt.
After setting things up, I check four places for exposed credentials: the invoking shell's environment, process arguments, shell history, and startup files such as .zshrc. I actually found a plaintext key in one of those files. A pasted shell configuration block used it as a fallback when an environment variable was missing. I changed it to read from Keychain and revoked the exposed key. Issuing a separate access key for each device also means that, if one device exposes its key, only that key needs to be revoked.
I learned three things while working with Keychain.
- An entered value can be truncated to 128 characters. Supplying a value through the prompt or standard input to
security add-generic-passwordtruncated it at 128 characters in my setup. The prompt does not display the input, and the confirmation is truncated in exactly the same way, so nothing looks wrong during entry. The OpenAI project key I was using began withsk-proj-and was 164 characters long, so it was truncated. For that key, I passed the value as an argument and accepted that it would briefly appear in the process list. After storing a value, I check its length, not just whether it exists. Exactly 128 characters is a warning sign of truncation in this workflow. - Updating an existing entry can be slow. Overwriting an entry took 20 or 30 seconds. Just after restarting the rotation worker, it once took nearly 4 minutes. Creating a new entry at the same time took 0.03 seconds. Deleting the old entry and creating a new one brought the operation down to 0.5 seconds. There is a brief gap between deletion and creation, but the launcher asks the credential server first, so it did not affect launches in this setup.
- Resetting the login password can isolate the entire login keychain. Changing the password without supplying the old one prevents macOS from re-encrypting the login keychain with the new password. Resetting it from another administrator account is one example. macOS instead renames the old keychain to
login_renamed_Nand creates an empty one. The isolated keychain still requires the old password that was last synchronized with it; a FileVault recovery key cannot unlock it. In my case, more than 90 entries were locked. A year-oldlogin_renamed_1was already there too, showing that an earlier reset had silently done the same thing. I could not remember the old password, so I reissued the keys. To prevent this, change the password while logged in through System Settings → Touch ID & Password → Change Password. That flow asks for the old password, allowing the keychain to be re-encrypted too.
Run rotation in the background and keep it alive on failure
One shell script handles rotation. It fetches a token once at startup and stores it in Keychain, then checks the token's status with the credential server every 10 minutes. If the account is close to its limit or the token is unusable, it fetches new credentials and replaces the cached copy. Logs contain status information, not token values.
I keep the script running with launchd. It is registered as a user LaunchAgent, with RunAtLoad starting it at login and KeepAlive restarting it after exit. A plist does not expand ~ or $HOME, so its paths must be absolute.
The first version exited with an error if it could not fetch the initial token. That caused a serious problem: launchd restarted the process after its restart interval, set to 30 seconds through ThrottleInterval. If the credential server was temporarily unable to issue a token, or the access key was missing from Keychain, the script exited and restarted repeatedly, hitting the server every 30 seconds. It restarted 1,700 times over two days when it could not obtain a token. I changed it to stay alive on failure. It waits inside the loop until the key appears, or until the next polling interval if token retrieval fails. For a supervised script, "exit on failure" effectively meant "retry every 30 seconds."
Gaps in the logs that looked like failures turned out to be sleep. When the Mac sleeps, the rotation worker sleeps too. Comparing sleep timestamps from pmset -g log with the gaps makes this clear. The credential server chooses the account with the most available capacity for each request, so frequent account changes in Codex's 10-minute refresh logs can be normal.
What is automatic and what still needs a person
I automated only the preparation of new credentials. Switching an already-running session remains a manual step.


Claude Code reads the environment variables once at startup, and Codex reads auth.json when its session starts. Codex renews the current account's tokens itself during use. In my observations, however, replacing the file externally with another account's credentials did not switch the running session. Even after the worker replaces the cached copy with B, the active session keeps making requests with A. Once A reaches its limit, that session cannot continue. Ending it and starting again through the launcher loads the latest credentials. Its history remains in the dedicated directory, so I can continue with --resume. Closing the Codex desktop app's window does not stop its process; it must be fully quit and reopened to read the new credentials.
For headless use in scripts, check the launch options too. With --bare, Claude Code does not read CLAUDE_CODE_OAUTH_TOKEN. I omit --bare when using the shared subscription token. Usage-based API keys have official mechanisms such as apiKeyHelper that can fetch keys again while running. This post uses subscription tokens passed through an environment variable, so I restart the session.
Operating rules
The setup rests on three principles. Separate accounts with configuration directories, and share working preferences through links. Pass credentials only to the process being launched. Store them in Keychain and run the rotation worker through launchd.
Five practical rules came out of operating it.
- Keep the shared account in a dedicated directory to avoid logging it out by accident.
- Keep background workers alive on failure. A supervisor that immediately restarts them can turn failure into a restart loop.
- Store credentials in Keychain and check their length after writing. To update an entry, delete it and create a new one.
- Change the login password through the normal password-change flow instead of resetting it without the old password.
- Automate preparing new credentials; restart sessions manually.
Comments
Korean and English pages share this conversation.
Loading comments…