When working with Claude Code, there are moments when another agent's help would be useful: creating a blog cover image, checking newly written code for gaps from a different perspective, or deciding which of two outputs to adopt. You can open Codex separately, or connect the process so that Claude Code passes it the work and receives the results.
The starting point was a question: “Is there a skill for using Codex from Claude Code?” After investigating seven candidates, including the official plugin, I found that the first distinction to make was less about how many plugins exist and more about how Codex is invoked and how its results are verified.
This post has two parts. First, I compare the official plugin with direct CLI calls. Then I look at their application to image generation, adversarial review, and A/B evaluation. For image generation, I checked the saved execution logs and PNG. The other two use cases remain designs that have not yet been run.
What Did I Actually Verify?
The initial research took place on September 6, 2026, in a Windows 10 environment. The report records Claude Code 2.1.263 and Codex CLI 0.153.4. While preparing this post, I checked the findings again against the official documentation and plugin source as of September 7. The distinctions below are the basis for reading this post.
| Subject | Verified | Not Yet Verified |
|---|---|---|
| Official plugin | Documentation and source structure; environment checks recorded as passing in the source material | Whether an actual review succeeds after installation |
| Image generation through direct CLI calls | One run, the resulting PNG, timing, and event logs | Repeated-run success rate and average latency |
| Adversarial review | Review of draft prompts, schemas, and wrappers | A verification loop against actual code |
| A/B evaluation | Designs for comparing outputs, comparing implementations, and visitor experiments | Comparative experimental results or conversion-rate improvements |
I did not install the official plugin. The ready: true in the source material records a check of the environment and authentication required to run it; it must not be read as meaning that every plugin feature worked correctly on this PC.
What Does the Official Plugin Connect?
OpenAI provides openai/codex-plugin-cc for Claude Code. The plugin I investigated was v1.0.6, and the code I inspected was at commit db52e28.
The invocation flow is as follows.
Claude Code의 /codex:* 명령
  → 플러그인의 Node 스크립트
  → 로컬 codex app-server
  → Codex 작업·리뷰
  → Claude Code로 결과 반환
Internally, the plugin starts a codex app-server process and exchanges requests through JSON-RPC. It is closer to a connection layer through which Claude Code invokes separate Codex tasks than a setting that adds a Codex model inside the Claude model. Execution code
The main commands are divided by role.
| Command | Purpose |
|---|---|
/codex:review |
General code review of changes |
/codex:adversarial-review |
Review focused on assumptions, design, and failure conditions |
/codex:rescue |
Delegate investigation or fixes to Codex |
/codex:transfer |
Transfer a Claude Code session to Codex |
/codex:status, /codex:result, /codex:cancel |
Check progress, retrieve results, and request cancellation |
Reviews and delegated fixes have different permissions. In particular, rescue may lead to work that can modify files, so it should not be treated like a read-only review. Receiving review results and verifying the changes are also separate things.
Installation and Things to Check on Windows
The official README gives the following installation procedure inside Claude Code. This reproduces the official installation instructions; it is not a record of installation completed during this investigation.
/plugin marketplace add openai/codex-plugin-cc
/plugin install codex@openai-codex
/reload-plugins
/codex:setup
Node and the Codex CLI must be available, along with authentication for Codex. It is best to check the official installation guide at installation time for detailed requirements and commands.
On Windows, installation is not the only thing to check; termination, cancellation, and background-process behavior also matter. For example, issue #530 reports that the Stop hook waited for a long time in a particular Windows 11 environment even with the review gate disabled. Issue #525 describes a failure to force-terminate a process because of Git Bash path conversion. The latter report also describes conditions under which a graceful cancellation request is possible, so summarizing it as “cancellation does not work at all” would overstate the report.
These are reports from other users, not results I reproduced on this PC. The fact that related issues were open when I checked is a reason to investigate before adoption, but does not establish that the same problems occur in every Windows environment.
When I checked on September 7, 2026, the most recent commit on the default branch was from July 8. The interval between commits alone cannot establish that maintenance has stopped. When adopting it, look at the issues and change history for the features you need.
How Does a Direct CLI Call Differ?
Another approach is to run codex exec from a Claude Code tool or project skill without going through the plugin. You define the recurring command, input prompt, and location for the results yourself.
| Comparison | Official plugin | Direct codex exec call |
|---|---|---|
| Execution path | Node script → app-server |
Run a single CLI task |
| Starting point | /codex:* commands and provided workflows |
Your own commands, skills, and scripts |
| Task management | Status, result, and cancellation commands provided | Manage termination and result files yourself |
| Result format | Follow the output format of the provided command | Choose text, JSONL, or JSON Schema output |
| What you maintain | Plugin version, hook behavior, and broker behavior | Paths, exit codes, timeouts, and result validation |
| Good fit | Use the supplied review and delegation flows directly | Customize a narrow, repeatable task |
The choice comes down to whether you need the conveniences of the official plugin or prefer simpler inputs and outputs while accepting more things to manage yourself. Direct calls bypass this plugin's hooks and broker, but do not eliminate compatibility issues in the Codex CLI itself.
The community alternatives I investigated also need to be distinguished by their execution paths. For example, codex-in-claude wraps codex exec in its own MCP server. By contrast, claude-codex registers Codex's built-in mcp-server. Both descriptions mention MCP, but they are different implementations.
What the current official documentation marks as deprecated is the codex mcp-server command. This must not be interpreted as meaning that every community wrapper using MCP has been discontinued. The official documentation points to app-server and the official Claude Code plugin as alternatives. MCP server documentation
The Basic Shape of a Direct Call
The following configuration example reads changes in a repository from Git Bash and writes the result to a file. It is not an exact copy of the command used for the image-generation probe.
mkdir -p review-output
codex exec --sandbox read-only --json \
 --output-last-message review-output/result.md \
 "변경 사항을 읽고 실패 가능성이 있는 지점을 근거와 함께 정리해줘. 파일은 수정하지 마." \
 > review-output/events.jsonl
Here, --json records runtime events as JSONL, while --output-last-message saves the final response in a separate file. For automated processing, --output-schema can specify the structure of the final response. Check the exit code, failure events, and whether the result file exists together. Valid JSON alone does not guarantee accurate content. Non-interactive execution documentation
Use Case 1: Image Generation, Verified Through Logs and Files
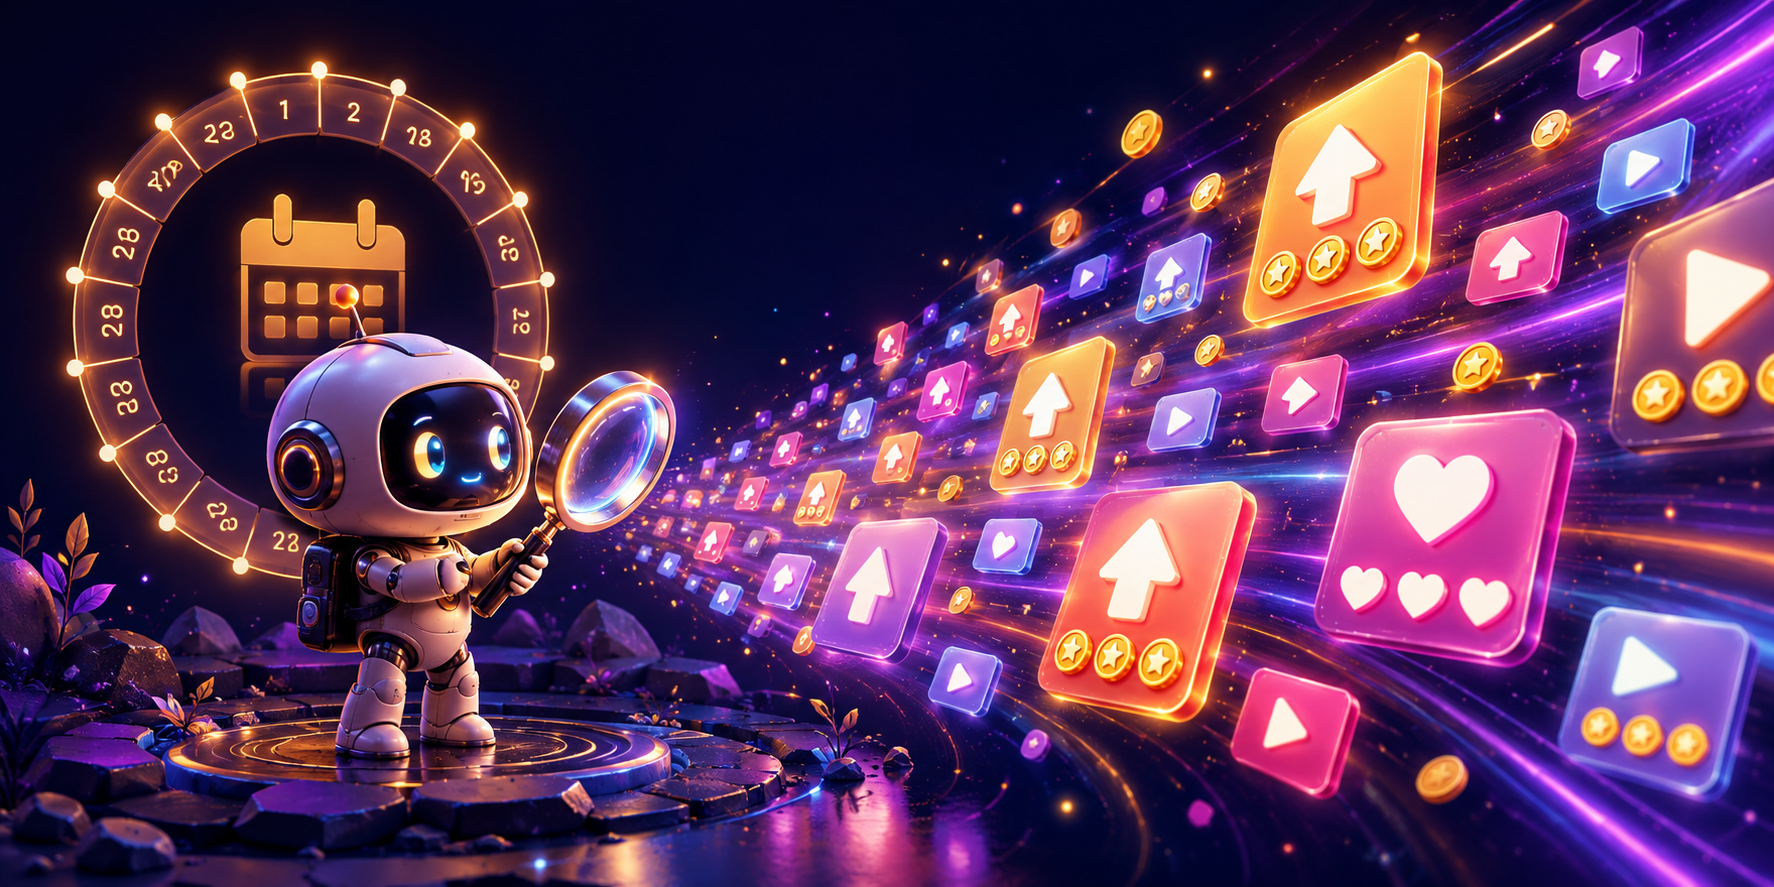
The task I actually ran called the Codex CLI from Claude Code to create a blog cover image. The prompt requested Codex's built-in image-generation tool and asked it to save the result as sample-a.png. The subject measured was a cover concept for last30days.
The verified path used codex exec to invoke the built-in image_gen. This was not an experiment using a separately obtained Images API key and an API script. The built-in tool's availability still needs to be checked for the environment and account being used. Codex image-generation guide
| Measurement | Result |
|---|---|
| Number of runs | 1 run |
| Wrapper start to finish | 77 seconds |
| Time reported by the image-generation tool | 38.4 seconds |
| Saved image | 1774 × 887 PNG, 2:1 aspect ratio |
| File size | 2,221,382 bytes |
| File verification | Matching SHA-256 hashes for the original saved by Codex and its copy |
The 77 seconds is not just image-model inference time. It is the full execution time, including task startup, context reading, image generation, file verification, and copying. It should not be compared with the tool's reported 38.4 seconds as though they were the same metric. Nor does one successful run establish average speed or repeatability.
The final usage event recorded 110,853 input tokens, of which 90,496 were cached, and 693 output tokens. These values describe that agent run; they are not a token cost for one image or a figure converted into money. Both the image-generation tool call and the agent's context processing need to be considered.
The practical lesson is that work remains after “an image was generated.” In the sample, marks resembling numbers remained around the calendar border despite a request for no text. Successful file creation and fulfillment of the visual requirements must be checked separately. Identify the result path for the current run, verify that the file really exists, check its dimensions and aspect ratio, and inspect whether its visual content is appropriate. Since several sessions may run simultaneously, it is also better to avoid simply picking whichever image file was created most recently.
Use Case 2: Design Adversarial Review to Produce Falsifiable Findings
Adversarial review is not a request to find as many defects as possible. It is a process of examining assumptions and failure conditions that the implementer may overlook from another perspective, and making the findings verifiable through code or tests.
A draft skill was written for this use case, but the actual verification loop was not run. The original draft also has two CLI-option locations that need to be fixed and rechecked on this PC. It is therefore not yet ready to install as a finished tool or to present as a method that “caught bugs.”
The core of the design is to separate the roles.
Claude Code: 요구사항과 변경 범위 정리
  → Codex: 읽기 전용으로 실패 조건·근거 검토
  → Claude Code: 지적을 코드·테스트로 재확인
  → 확인된 지적 수정
  → 테스트와 필요한 재검토
Give the reviewer a baseline for the changes, the target files, and the behavior that must be preserved. It is important that the reviewer read the actual changes and requirements, rather than relying only on the author's conclusion that the implementation is good.
The result should contain at least the following information.
- What could go wrong?
- What input or execution sequence triggers it?
- Which file, function, or code supports the finding?
- What check could reproduce or disprove it?
- What remains unverified?
For example, “There is a branch that changes the state to completed even when the save request fails, which can be checked with a test returning a failure response” is more useful for follow-up work than “Exception handling is insufficient.”
In operation, content judgments and execution status also need separate records. A completed review that found no issues must not be treated as the same approval as a timeout that produced no result. The design keeps failed runs marked as failures, caps the number of iterations, and accepts actual fixes only after checking their test results.
You can use the official plugin's /codex:adversarial-review, or create your own result format directly with codex exec --output-schema. That plugin feature and the custom draft skill examined here are separate implementations.
Use Case 3: Decide What You Are Comparing Before an A/B Evaluation
While organizing the report, I also found that the term “A/B testing” was being used for several different activities.
| What to compare | Required setup | What the result can tell you |
|---|---|---|
| Choose between two images or drafts | The same evaluation criteria; two options with their authors hidden | The model's preference and reasoning under those criteria |
| Compare Claude and Codex implementations | The same requirements and baseline code, separate workspaces, and identical tests | A comparison of implementation and verification results under defined conditions |
| Compare actual visitor responses | Random assignment, metric collection, and a sufficient sample | Experimental results about user behavior |
The first approach uses an LLM as a judge. For two blog covers, you can first define criteria such as “Does it convey the topic?”, “Is it readable on a small screen?”, and “Is there room for an overlaid title?” Hide the author or generation-model names, swap A and B, and present them again to check whether position affects the judgment. If the judgments conflict, leave the choice for human review instead of forcing a winner.
Models can be influenced by response order or length. This calls for pairwise comparisons with clear criteria, rather than just a single score, along with a process to check agreement with human judgment. OpenAI evaluation best practices
The second approach is an implementation experiment. Since changes can become mixed if two agents work in the same repository at once, the idea is to use separate workspaces created from the same baseline commit. Judging correctness should involve the same tests, build, and requirements checks, as well as the persuasiveness of the explanation. If the conditions differ, model differences become difficult to separate from workspace differences.
The third approach, a visitor experiment, requires separate instrumentation. A model preferring cover B is not evidence that readers clicked B more often. Improvements in click-through or conversion rates cannot be claimed before assigning actual traffic and measuring behavior. This investigation reviewed only the designs for all three types.
Separate Costs and Permissions by Task, Too
Using a plugin does not make Codex free. It uses the local Codex authentication: a ChatGPT login draws on that plan's Codex allowance, while an API-key login follows separate OpenAI Platform API billing. This image probe ran in the ChatGPT-login environment recorded in the report. Codex authentication, Pricing and usage guide
Claude usage is also incurred when Claude Code prepares the work and reads the results. The comparison therefore needs to cover the whole task: output quality, number of calls, context size, waiting time, and time spent on human verification.
Set permissions according to the role. Start code review in read-only mode, and grant the necessary scope of write access to tasks that need to create files. Read-only restricts file-writing permissions for tools run by Codex; it does not mean that the material is not sent to an external model. Which files and context are transmitted needs to be checked separately.
Applying This to This Blog
The operating approach I have outlined at this stage is clear. For image generation, start with the one verified path and check the result file, dimensions, and content every time. For code verification, narrow the scope in read-only mode and request findings whose evidence can be checked with tests. To choose between two outputs, define evaluation criteria first and retain a final human decision.
The official plugin is a candidate when you want to use the supplied review and task-management commands. Direct CLI calls are worth considering when, as with this blog, you want to begin with narrow tasks that have defined inputs and result files. With either path, separating responsibility for creation, review, and adoption, and retaining execution results is the starting point for using the two agents together.
This post was written from research material and an image-generation probe dated September 6, 2026, and checked against official documentation and plugin source on September 7. Image generation was measured once; this post does not claim completion of the official plugin installation, actual reviews, or A/B experiments. Local environment information in the original logs has been excluded from the public text, leaving only the relevant measurements.
Comments
Korean and English pages share this conversation.
Loading comments…